Companies handling medical or financial records face strict rules on sharing personal information. Manual redaction fails at scale due to human error and limited precision. Traditional methods struggle with degraded text and complex field-level logic.
Amazon Bedrock Data Automation replaces custom models
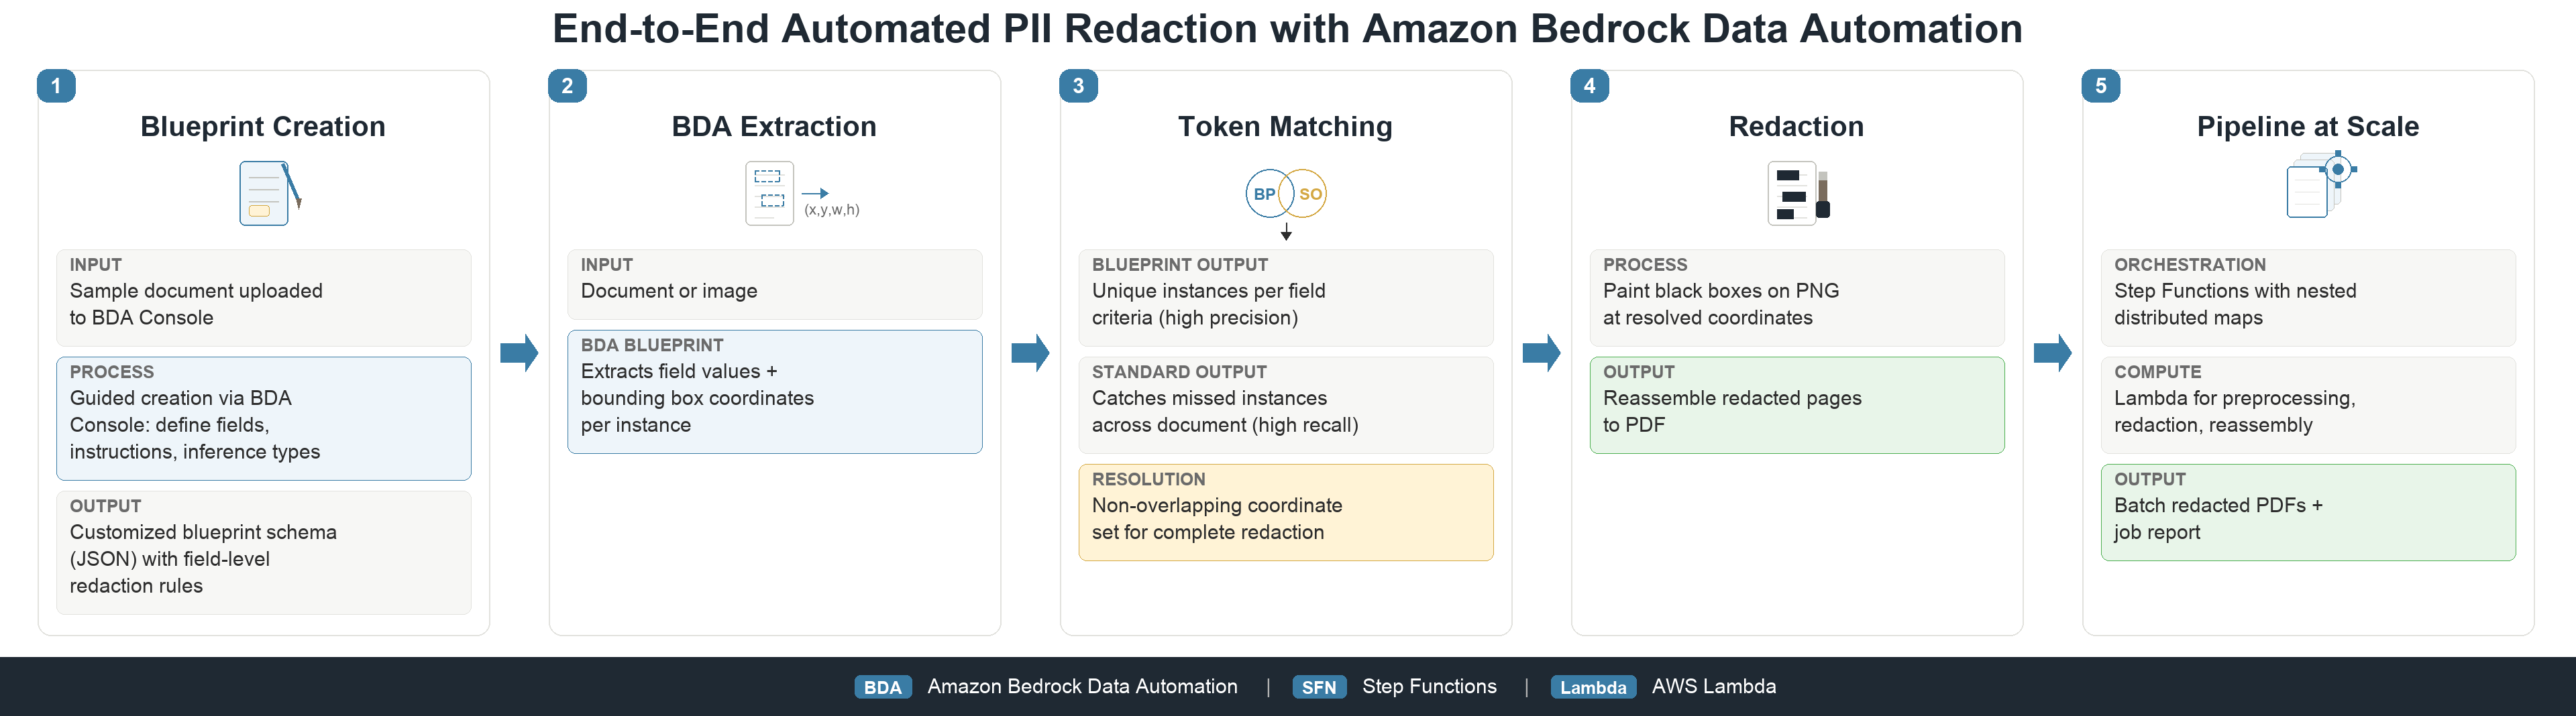
Amazon Bedrock Data Automation extracts structured data from unstructured documents. It uses foundation models to understand layout, labels, and context holistically. The service returns confidence scores and bounding box coordinates for each detected item.
Custom blueprints define exactly what to redact
Users create a blueprint specifying which fields contain sensitive information. The system distinguishes between different types of dates or names on a page. This allows precise removal of only the data that requires protection.
A serverless pipeline applies the rules automatically
The solution combines Bedrock Data Automation with AWS Step Functions and Lambda. It converts PDFs to images, applies black-box redaction, and handles post-processing. The same pipeline works for many use cases by changing the blueprint schema.
Why it matters
This approach removes the need for custom machine learning models trained on specific documents. It reduces operational costs by automating a task that previously required specialized staff. Safety improves because the system applies consistent rules across thousands of records. Source: https://aws.amazon.com/blogs/machine-learning/build-a-serverless-pii-redaction-pipeline-with-amazon-bedrock-data-automation/