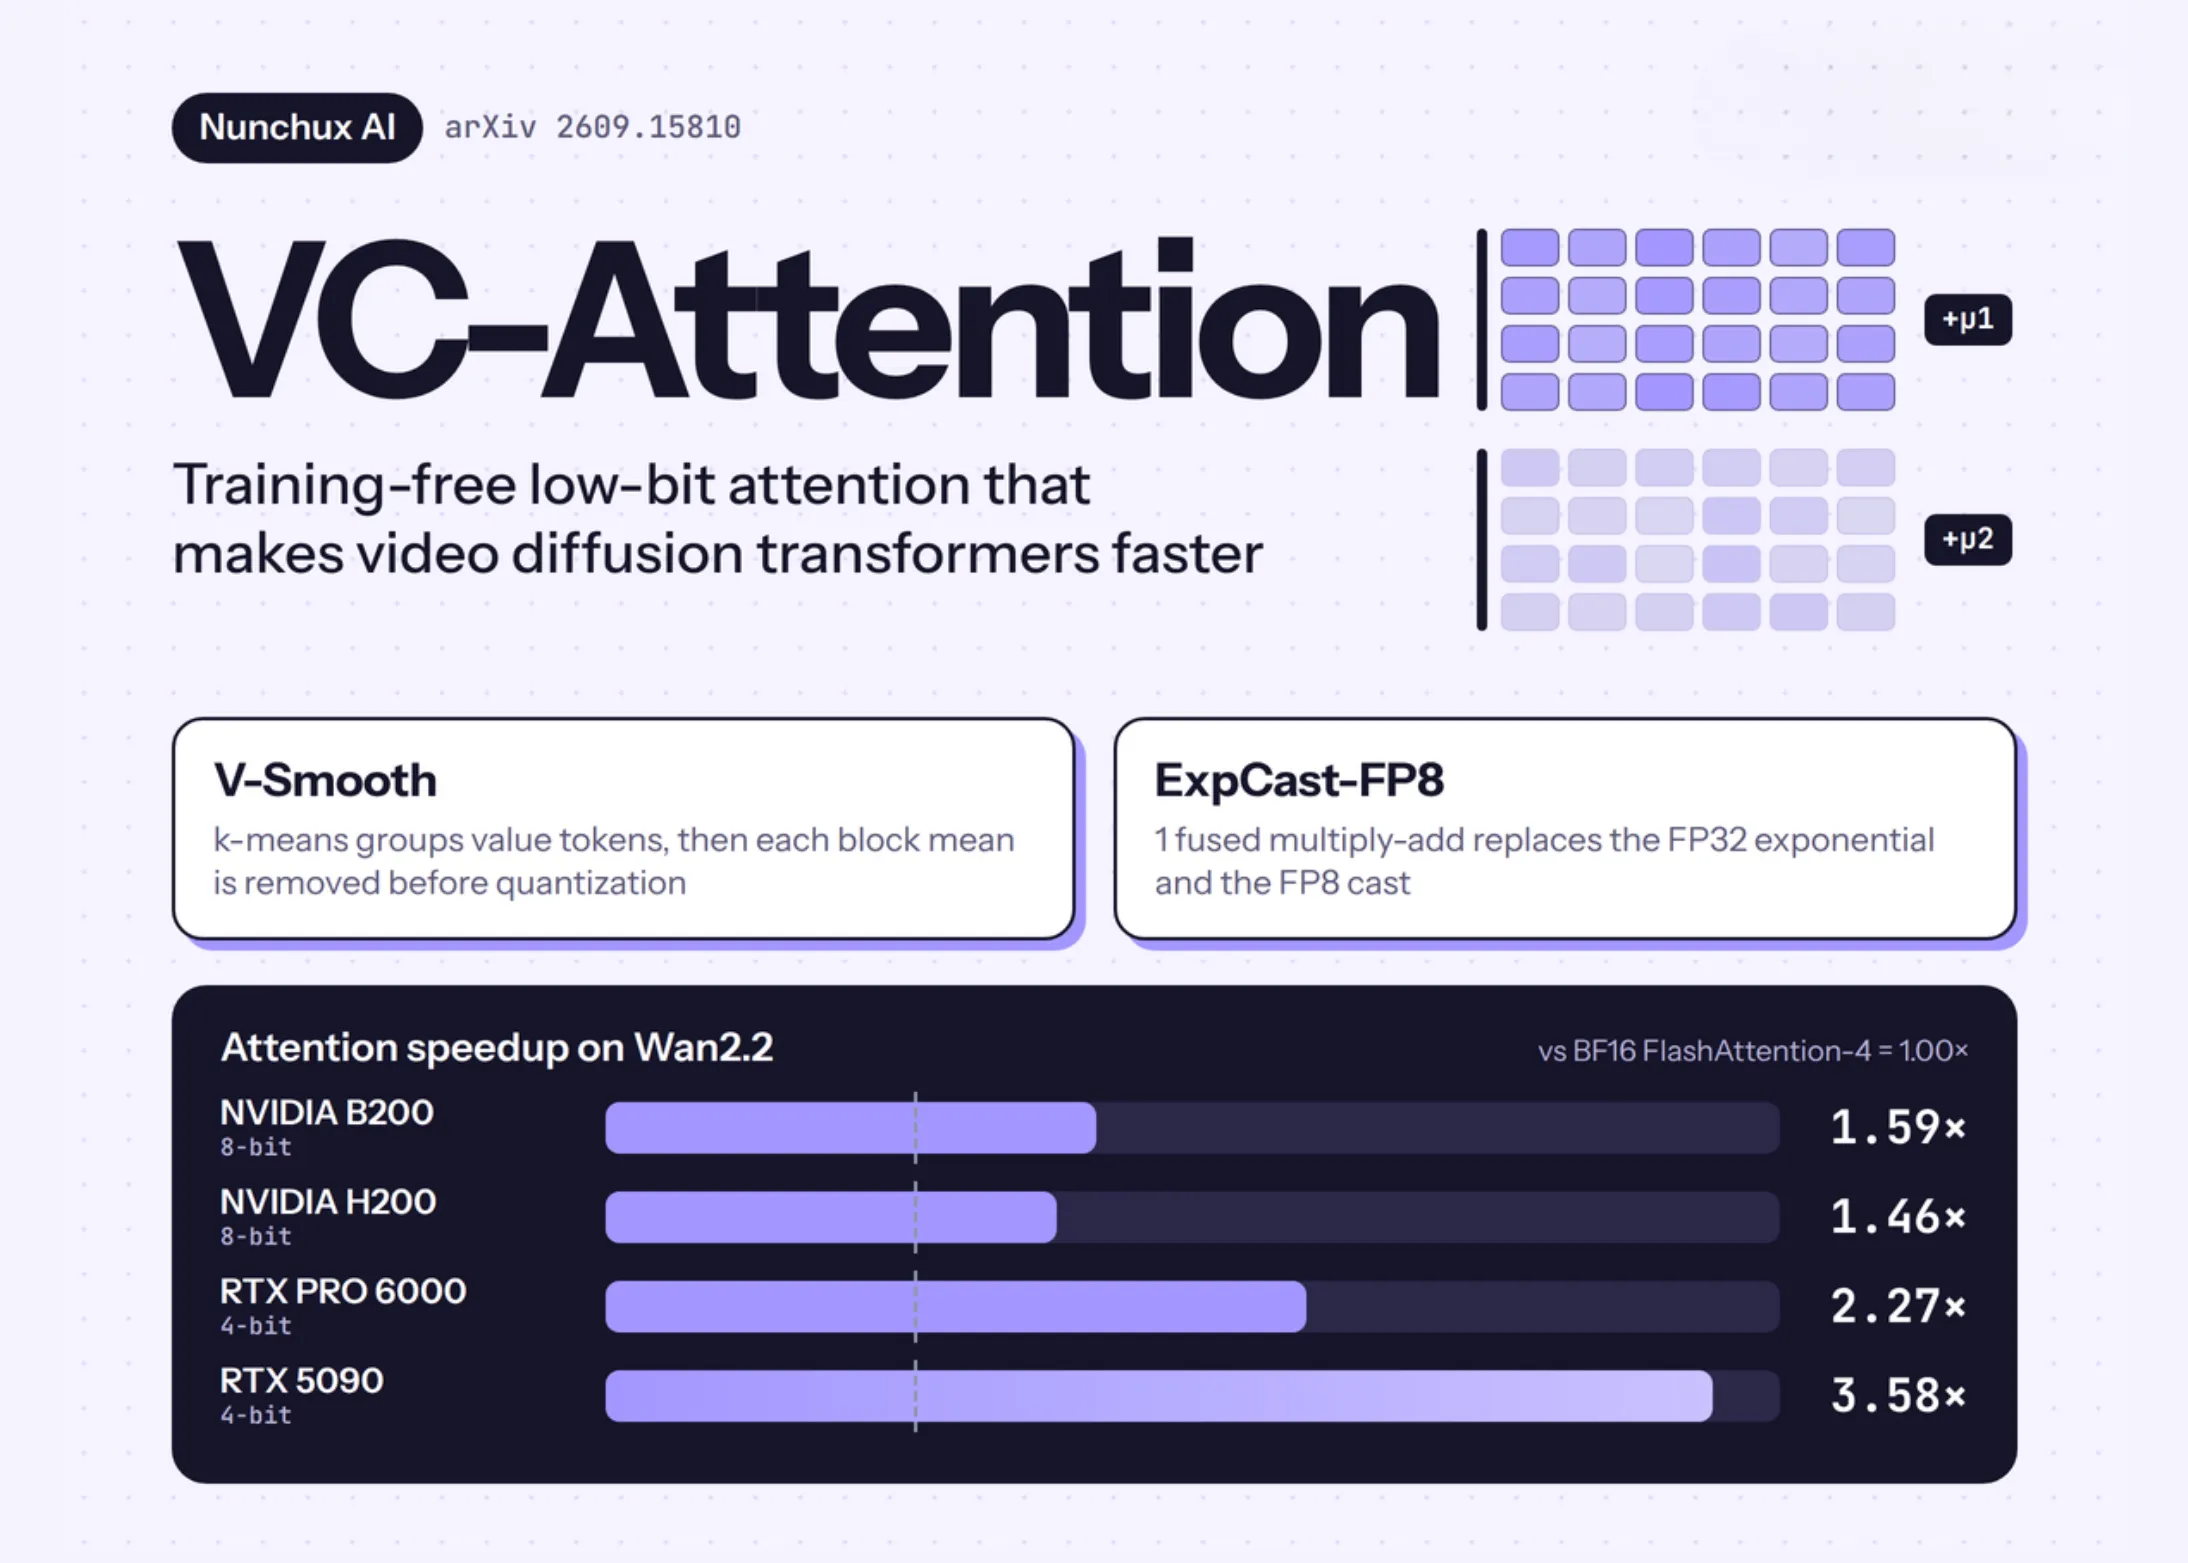
Nunchux AI released VC-Attention for video Diffusion Transformers.
This kernel fixes value quantization error and slows down attention.
Video clips flatten into long token sequences. Full self-attention consumes most generation time on modern hardware.
How It Works
The method uses group-based clustering to handle value outliers.
It subtracts block means before quantizing residuals at 8 or 4 bits.
A fused multiply-add replaces the expensive FP32 exponential calculation.
Hand-written CUDA fusion cuts preprocessing time significantly on Blackwell chips.
Why it matters
VC-Attention runs six times faster than SageAttention2 on B200 GPUs.
It maintains high fidelity across four open-weight video models.
The approach works with existing sparse attention and multi-GPU setups.