AI1 min read
SK Hynix talks with Intel on US memory chip factory
SK Hynix discusses building RAM chips in the US with Intel. No final plans or decisions have been made yet.
From TechCrunch AI
Blog
Daily notes on new models, LLM releases, agent frameworks and AI research, written from the sources we follow and delivered as a newsletter every day.
Get the daily issue
Every new post of the day, in one email. Confirmation required.
AI1 min read
SK Hynix discusses building RAM chips in the US with Intel. No final plans or decisions have been made yet.
From TechCrunch AI
AI1 min read
National outcry against data center construction has spread to Philadelphia, where officials suggested possible construction in a neighborhood already impacted by a now-defunct oil refinery.
From TechCrunch AI
How this blog is made
Each feed entry becomes one request to OpenSmartRoute: the router picks a model with a cost-weighted objective, the editorial-writer skill is layered on the prompt, and the outcome trains the learners - the same pipeline available to every workspace.
Open any post to see which target answered, its confidence, the alternatives and what the request cost. Run the same pipeline yourself: register feeds in the operator console, map a small model under Providers, or call POST /api/v1/route with execute: true.
The AI frenzy could push U.S. data centers to become one of the largest consumers of natural gas in the world.
From TechCrunch AI
LLMs1 min read
How can a 30B-parameter model activate only 3B parameters per token, and still use the capacity of the larger model? Nemotron 3.5 Lightning illustrates the...
From NVIDIA technical blog
LLMs1 min read
For operators of large-scale AI factories, maximizing continuous output is essential for productivity. In massive-scale AI training, every GPU in the cluster...
From NVIDIA technical blog
AI1 min read
Jensen Huang publicly stated Nvidia will not halt AI development following a phone call with President Trump, who expressed concerns about slowing AI progress and potential external pressures. The conversation highlighted broader public sentiment regarding data center construction and AI capabilities.
From TechCrunch AI
AI1 min read
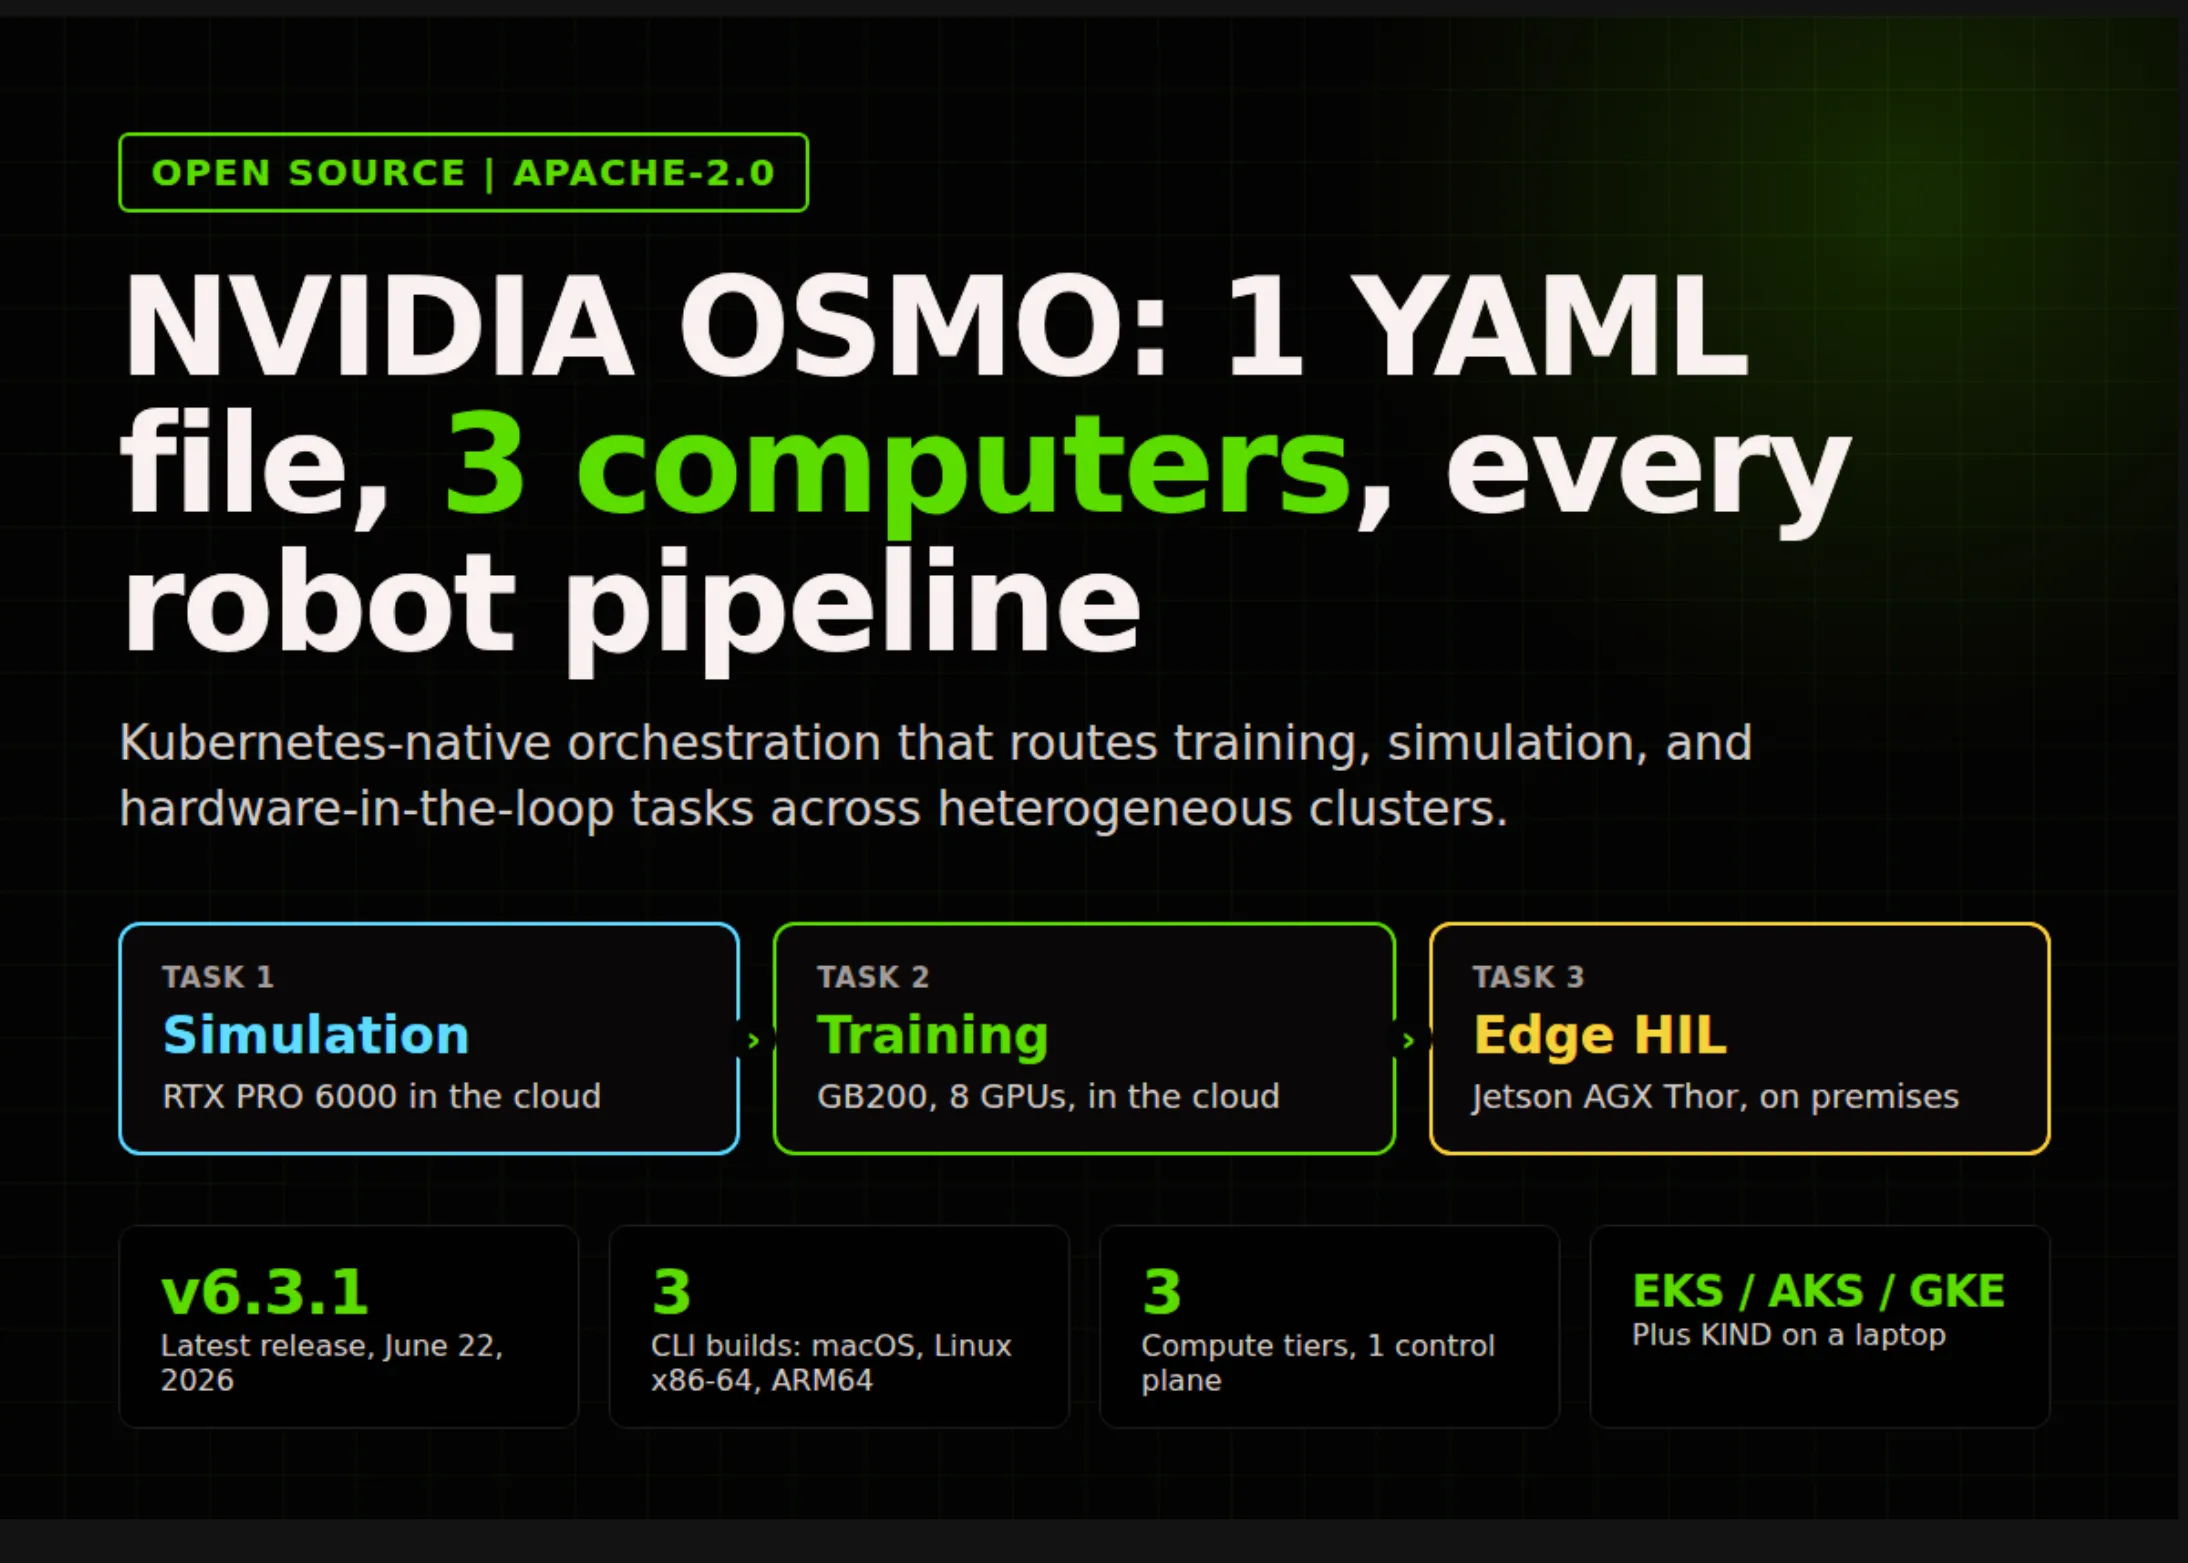
OSMO is an open-source Kubernetes orchestrator that allows engineers to manage AI training, simulation, and robot testing across diverse compute environments – from data center GPUs to edge devices – defined by a single YAML file. This simplifies pipeline management and reduces infrastructure complexity.
From MarkTechPost
AI1 min read
Nscale, an AI data center startup, has appointed former OpenAI CEO Fidji Simo to its board as it prepares for a potential IPO this fall. The addition of Simo, alongside other tech executives, reflects the company’s growing valuation and fundraising efforts.
From TechCrunch AI
LLMs1 min read
NVIDIA’s BioNeMo Inference Runtime accelerates biomolecular structure prediction at scale, allowing for efficient processing of large proteome workflows. This enables faster insights from complex biological data.
From NVIDIA technical blog
LLMs1 min read
A new approach enables user identity to be carried across federated Kubernetes and AI platforms, supporting workflows from central portals to dataset access and notebook launching.
From NVIDIA technical blog
LLMs1 min read
NVIDIA's blog discusses using speculative decoding to accelerate large language model inference while preserving accuracy, part of an AI model co-design series.
From NVIDIA technical blog
LLMs1 min read
Meta's Muse Glimmer is a 30-billion parameter open-weight dense model with a 120K+ context window, designed for local AI applications and open source deployment.
From NVIDIA technical blog
LLMs1 min read
NVIDIA Groq 3 LPX is an AI inference accelerator designed for the Vera Rubin platform, enabling ultrafast interactivity with long context windows.
From NVIDIA technical blog
LLMs1 min read
NVIDIA introduces DSX MaxLPS to improve AI factory performance per watt, addressing power constraints in industrial AI systems.
From NVIDIA technical blog
LLMs1 min read
The article discusses methods for organizations to size GPUs effectively for AI inference, balancing performance and total cost of ownership without overspending.
From NVIDIA technical blog
LLMs1 min read
NVIDIA TensorRT Model Connect allows engineers to deploy open AI models from checkpoint to inference using just two commands. This simplifies the deployment process and reduces the need for model-specific conversions.
From NVIDIA technical blog
LLMs1 min read
NVIDIA’s Spectrum-X Ethernet is designed to address the bandwidth challenges of distributed model training across large GPU deployments. This new technology allows for faster data transfer, crucial for scaling generative AI workloads.
From NVIDIA technical blog
LLMs1 min read
NVIDIA NVLink Fusion expands NVHBM capabilities, allowing for increased bandwidth and reduced latency between GPUs. This facilitates the execution of larger AI models and complex reasoning workloads within next-generation AI infrastructure.
From NVIDIA technical blog
LLMs1 min read
The NVIDIA Vera CPU features Olympus cores optimized for maximum single-threaded performance. This allows agents to execute more critical paths on the CPU, improving response times and overall efficiency in agentic AI applications.
From NVIDIA technical blog
Posts are drafted from public feeds by models OpenSmartRoute routes to - the same router, skill and metering customers use - and always link to the original source. Corrections: support.
Archive (34)